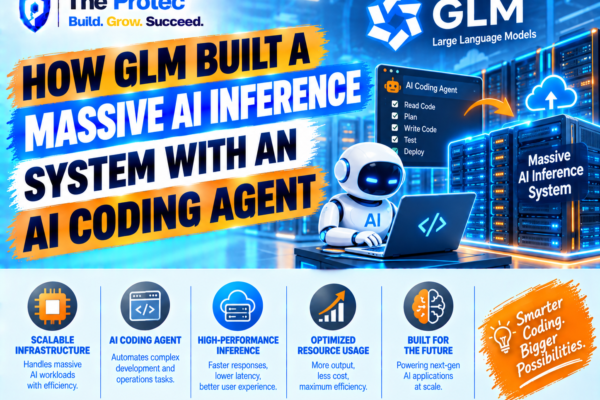
How GLM Built a Massive AI Inference System With an AI Coding Agent
GLM’s large-scale inference platform shows how GPU orchestration, distributed serving, and AI-assisted engineering are converging into a new model for building AI infrastructure.
GLM’s large-scale inference platform shows how GPU orchestration, distributed serving, and AI-assisted engineering are converging into a new model for building AI infrastructure.
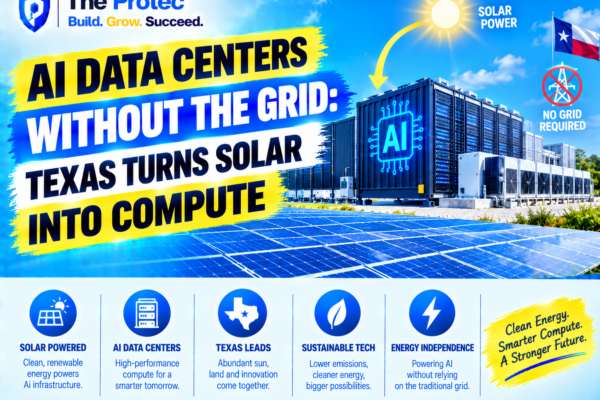
Texas solar farms increasingly produce electricity when the grid cannot fully absorb it. Co-located AI data centers could convert that curtailed energy into useful computing, provided operators solve the challenges of intermittent power, cooling, connectivity, and workload scheduling.
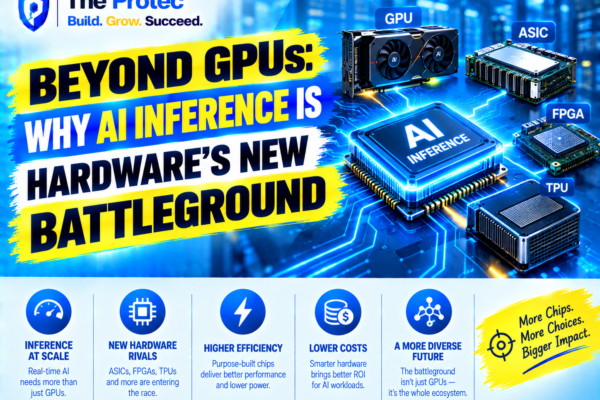
The AI hardware race is shifting from training giant models to serving them efficiently. Here is how GPUs, specialized accelerators, memory systems, and rack-scale architectures are competing for inference workloads.
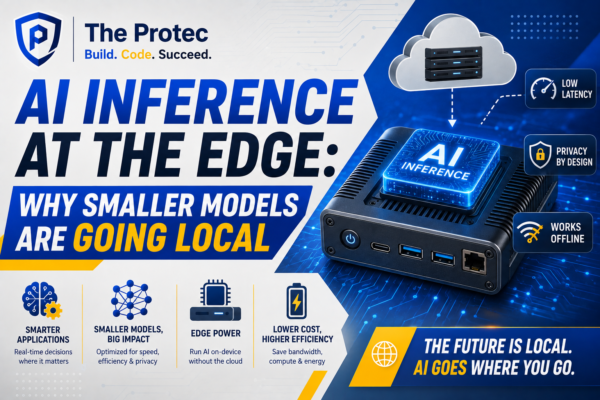
Smaller AI models are shifting inference from centralized clouds to phones, laptops, vehicles, and smart devices, delivering faster responses, stronger privacy, and lower connectivity costs.

Discover how real-time AI processing transforms streaming data architectures, enabling intelligent insights and rapid decisions in dynamic environments.