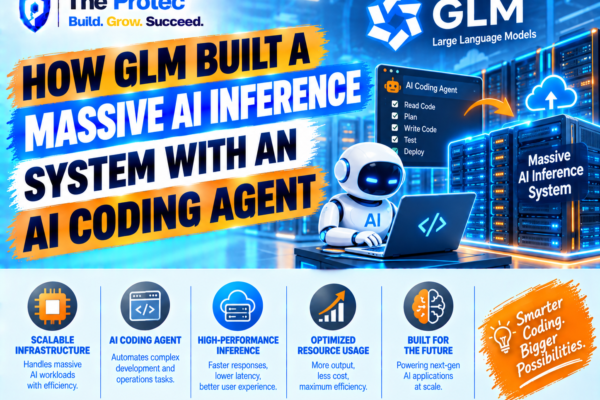
How GLM Built a Massive AI Inference System With an AI Coding Agent
GLM’s large-scale inference platform shows how GPU orchestration, distributed serving, and AI-assisted engineering are converging into a new model for building AI infrastructure.
GLM’s large-scale inference platform shows how GPU orchestration, distributed serving, and AI-assisted engineering are converging into a new model for building AI infrastructure.
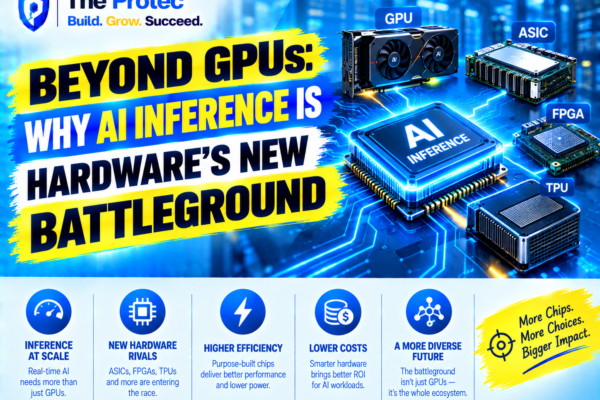
The AI hardware race is shifting from training giant models to serving them efficiently. Here is how GPUs, specialized accelerators, memory systems, and rack-scale architectures are competing for inference workloads.