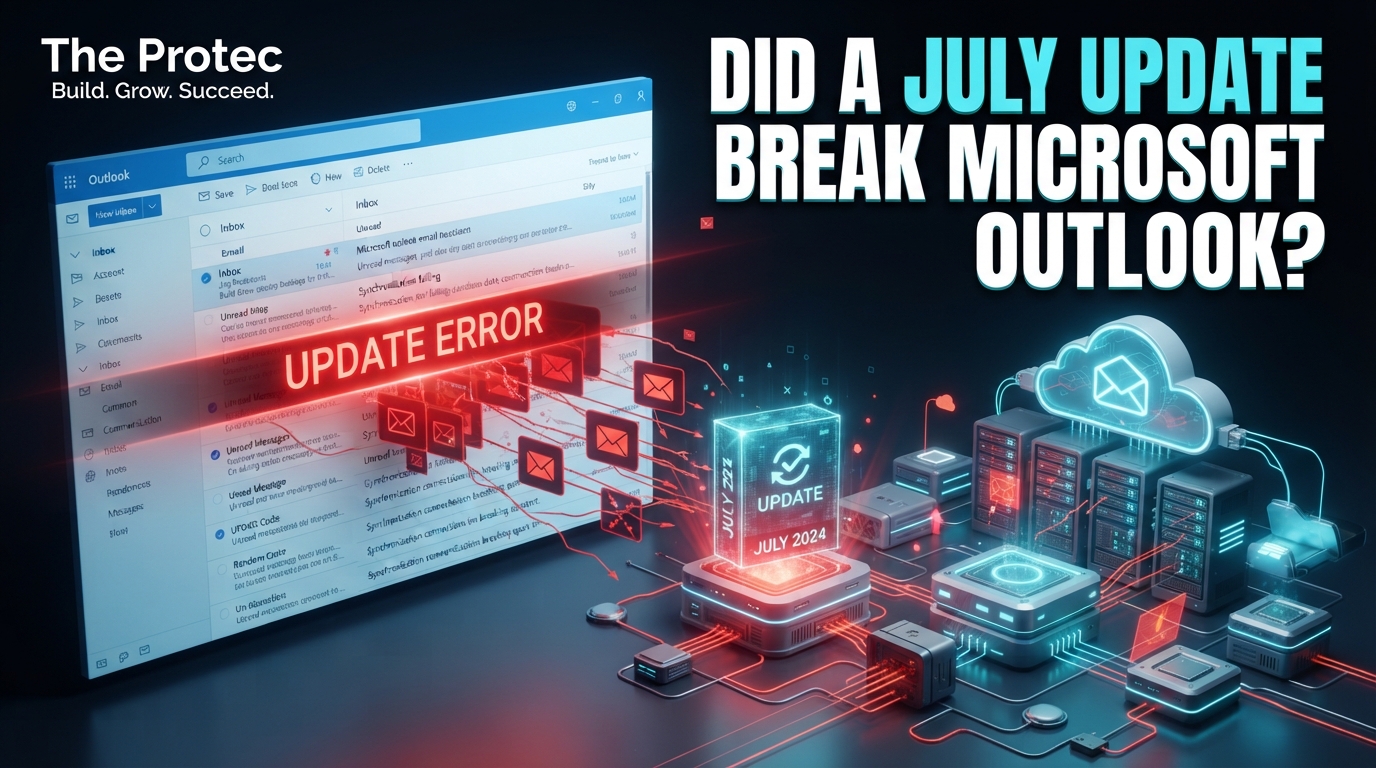
The November 12 email disruption initially looked like a broad infrastructure breakdown with no simple explanation. Microsoft has now disclosed the Microsoft Outlook outage root cause: a software defect introduced by a July update to network gateway servers. The dormant flaw surfaced when a Microsoft Teams failover increased traffic at the same time that nearly 14% of gateway capacity was unavailable, producing a cascading server failure that disrupted Exchange Online, Outlook and other Microsoft 365 services worldwide.
Microsoft detailed those findings in a preliminary post-incident report issued on November 15. The company said the defect created lock contention inside an internal Windows process, driving CPU and memory consumption upward until servers stopped responding. At the worst point, more than 80% of the affected server fleet was unresponsive.
Looking for the original incident coverage? Read The Protec’s report, Microsoft Outlook outage: What Happened to 365, Teams and Copilot, for the November 12 timeline, user symptoms, affected services and troubleshooting guidance. This follow-up focuses on Microsoft’s subsequent technical explanation rather than repeating that coverage.
What Microsoft says caused the global Outlook outage
The incident began with a Microsoft software defect that had existed in production since July. The update was intended to modify software running on Microsoft’s network gateway servers, which help direct and manage traffic entering services such as Exchange Online. It also introduced a defective code path capable of creating severe contention around a shared software lock.
A lock is a common synchronization mechanism used to prevent multiple threads from changing the same resource simultaneously. Under normal conditions, a thread briefly acquires the lock, completes its task and releases it. With the July defect, many threads could become stuck competing for the same lock. Instead of completing work efficiently, they waited, retried or accumulated behind the blocked resource.
That contention consumed increasing amounts of processor time and memory. Gateway servers became slow and then unresponsive, pushing traffic toward other machines that were still operating. Those servers subsequently faced heavier loads and encountered the same defect, extending the failure across the fleet.
The July update did not immediately cause an outage because ordinary traffic did not activate the defective path at a damaging scale. It took a specific combination of conditions on November 12 to expose it:
- A Microsoft Teams failover shifted additional traffic to the primary network gateway.
- Nearly 14% of the gateway fleet’s capacity was already unavailable.
- The remaining servers had to absorb an unusually concentrated workload.
- Lock contention accelerated as concurrency and resource pressure increased.
- Failing servers transferred still more work to healthy servers, creating a cascade.
This explanation is materially different from saying that excessive traffic alone caused the outage. Heavy load was the trigger, but Microsoft’s preliminary findings identify defective gateway software as the underlying cause.
How a Teams failover affected Exchange Online and Outlook
Cloud services may appear separate to customers while depending on shared infrastructure behind the scenes. Outlook clients connect to Exchange Online for mailbox access, but those connections can pass through common networking, routing, authentication and gateway layers also used by other Microsoft 365 workloads.
During the incident, a Microsoft Teams failover increased traffic reaching the primary gateway environment. That did not mean Teams itself contained the Outlook defect. Rather, the failover changed the traffic pattern hitting a shared infrastructure layer where the dormant gateway flaw was present.
Once gateway servers stopped responding, Exchange Online could not reliably accept or route client requests. Users experienced symptoms such as Outlook connection failures, delayed or inaccessible mail and problems reaching Microsoft 365 functions. Other workloads depending on the same infrastructure could also degrade even if their application code remained healthy.
This shared dependency explains why the Microsoft Exchange Online outage became so broad. A cloud provider can have healthy mailbox databases and functioning application servers yet still suffer a major email failure when the network gateways in front of them cannot process requests.
Why newer hardware made the software defect worse
One counterintuitive detail in Microsoft’s preliminary report was that the defect produced more serious effects on newer servers with greater numbers of CPU cores. More processing power would normally improve resilience, but concurrency defects do not always behave like ordinary capacity constraints.
A higher core count allows more threads to execute at the same time. If many of those threads need the same software lock, additional parallelism can create more competitors for that single protected resource. The server has more theoretical processing capacity, yet threads spend increasing time waiting for or repeatedly attempting to obtain the lock.
The result resembles adding lanes to a highway that all converge at one blocked toll booth. More vehicles can approach simultaneously, but the bottleneck becomes more crowded rather than more efficient. Memory pressure can also rise as pending work and waiting threads accumulate.
That behavior helps explain why older assumptions about server capacity did not protect the fleet. Capacity planning based mainly on CPU quantity, average utilization or request throughput can miss synchronization bottlenecks that become worse as hardware gains more cores.
Why Microsoft’s load testing did not expose the flaw
Microsoft said its predeployment testing did not reproduce the production conditions required to activate the defect at outage scale. A useful load test must model more than a high number of requests. It must also reproduce concurrency, hardware characteristics, traffic distribution, failure states and the way workloads move during failover.
The July code could therefore pass ordinary functional checks and synthetic load tests while retaining a serious regression. If a test environment did not combine newer high-core hardware, reduced gateway capacity and the traffic concentration caused by failover, it might never generate enough simultaneous lock competition to reveal the problem.
The incident illustrates an important limitation of averages. A system may pass tests at expected total traffic levels but fail when requests become concentrated on fewer machines. Similarly, a test using a balanced fleet may not represent production when nearly 14% of capacity is missing.
Effective software regression testing for distributed cloud platforms must include compound failures. Providers need to test what happens when a failover occurs during maintenance, partial capacity loss or another degraded state—not only when every backup system is fully available.
Why automated recovery and rollback were insufficient
Cloud platforms normally use automated health checks to remove failed machines, restart processes and redistribute traffic. Those safeguards were not enough because the same defective code existed throughout the relevant gateway fleet. Moving requests away from one unhealthy server simply increased pressure on other servers capable of encountering the same lock contention.
Restarting a machine could temporarily clear exhausted resources, but it did not remove the software defect or reduce incoming demand. Once the restarted server rejoined the fleet, the same traffic conditions could drive it back into failure.
A conventional rollback was also complicated by the age of the change. The defect had been deployed in July and remained dormant for months. By November, the operational environment had moved beyond that release, making a broad rollback less direct than reverting a newly deployed update immediately after an error appears.
Engineers ultimately restored service by deploying a targeted patch that returned the defective code path to its previous known-good state. This removed the lock-contention behavior while avoiding the wider risks of rolling back months of unrelated platform changes. As patched servers recovered and rejoined the available pool, gateway capacity stabilized and Microsoft 365 traffic could be processed normally.
Outage timeline and preliminary findings
- July: Microsoft deployed the network gateway software update that introduced the defect.
- November 12: A Teams failover increased traffic to the primary gateway while nearly 14% of gateway capacity was unavailable.
- During the disruption: Lock contention exhausted CPU and memory, causing a cascading failure. More than 80% of servers were unresponsive at the worst point.
- Recovery: Engineers deployed a patch restoring the affected code path to its previous known-good state.
- November 15: Microsoft issued its preliminary post-incident report describing the defect and contributing conditions.
- November 20: Microsoft said it expected to publish a final post-incident report with completed findings and corrective actions.
These details should be treated as preliminary until the final Microsoft post-incident report is available. The final investigation could refine the sequence, identify additional contributing factors or provide more detail about preventive measures. Customers can monitor official incidents and advisories through the Microsoft 365 service health dashboard.
Nothing in the preliminary account indicates that the outage resulted from a cyberattack. Microsoft attributed it to a software regression, constrained capacity and failover-driven traffic inside its cloud infrastructure.
Lessons for cloud infrastructure reliability
Test realistic combinations of failure conditions
Load testing should model partial fleet loss, uneven traffic, failovers and production hardware—not merely expected request volume. The most dangerous defects often appear only when several manageable problems occur together.
Design failover as a capacity event
A failover is not successful simply because traffic moves. The destination must have enough usable capacity to absorb that traffic without triggering hidden bottlenecks. Reserve capacity should account for maintenance, failed nodes and unexpected demand at the same time.
Test software on current hardware
Newer processors can change thread scheduling and contention patterns. Regression suites should cover the actual range of CPU architectures and core counts deployed in production, especially for synchronization-sensitive gateway software.
Keep targeted recovery paths available
When a defect remains dormant for months, rolling back an entire release may be impractical. Feature isolation, reversible code paths and narrowly scoped emergency patches can provide safer recovery options.
Disaster recovery plans must account for dependencies beneath individual applications. Exchange Online, Teams and other products can be affected together when a shared gateway or identity layer fails. Organizations should maintain alternate communication channels and business continuity procedures that do not depend on the same cloud control plane.
Frequently asked questions
What was the Microsoft Outlook outage root cause?
Microsoft’s preliminary investigation identified a software defect introduced in a July update to network gateway servers. Under increased traffic, the defect caused lock contention inside an internal Windows process, exhausting CPU and memory and making servers unresponsive.
Why did a July defect wait until November 12 to cause an outage?
The flaw required an unusual combination of high concurrency and reduced capacity. A Teams failover increased traffic to the primary gateway while nearly 14% of gateway capacity was unavailable, activating the dormant defect at scale.
Why did automatic failover not solve the problem?
The defective code was present across the gateway fleet. Redistributing traffic placed additional pressure on other susceptible servers, allowing the failure to cascade instead of isolating it.
How did Microsoft restore Exchange Online and Outlook?
Engineers deployed a patch that returned the defective code path to its previous known-good state. This stopped the lock-contention behavior and allowed gateway capacity to recover.
Are Microsoft’s findings final?
No. Microsoft described the November 15 report as preliminary and said a final report was expected on November 20. The final version may add technical details, corrective actions or refinements to the incident sequence.
What happens next
The final report will be important because the immediate defect is only part of the story. Customers will want to know how Microsoft plans to improve production-scale testing, detect lock contention earlier, preserve gateway headroom and prevent one workload’s failover from overwhelming shared infrastructure.
For now, the preliminary explanation shows how a months-old software regression, a temporary capacity deficit and a routine failover combined to produce a global Microsoft 365 email outage. It is a reminder that cloud infrastructure reliability depends not only on redundancy, but on whether that redundancy has been tested under the complicated conditions in which it may actually be needed.