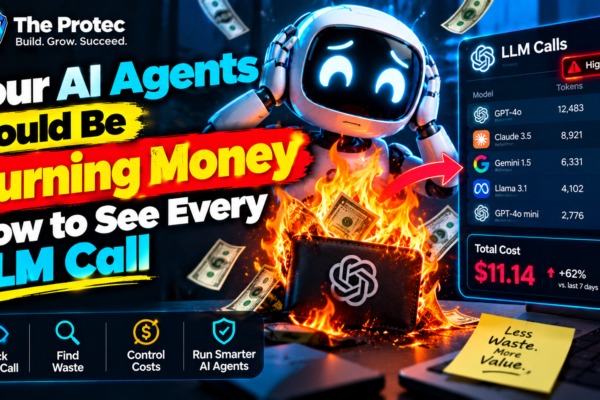
Your AI Agents Could Be Burning Money: How to See Every LLM Call
Provider dashboards reveal the bill, but not always the agent behavior behind it. Learn how an LLM proxy exposes request-level costs, latency, failures, routing, and token usage.
Provider dashboards reveal the bill, but not always the agent behavior behind it. Learn how an LLM proxy exposes request-level costs, latency, failures, routing, and token usage.
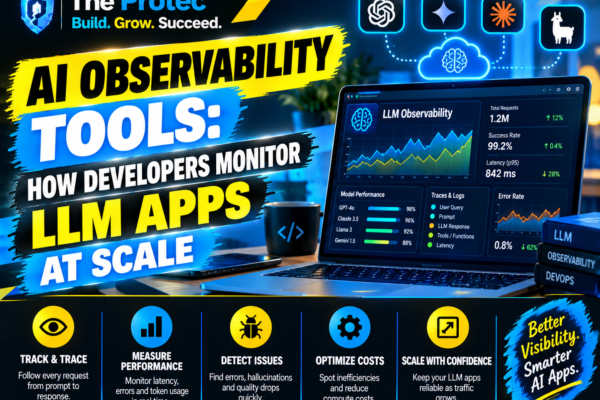
Explore how developers use AI observability tools to trace prompts, detect hallucinations, control token costs, evaluate outputs, and debug production LLM applications.