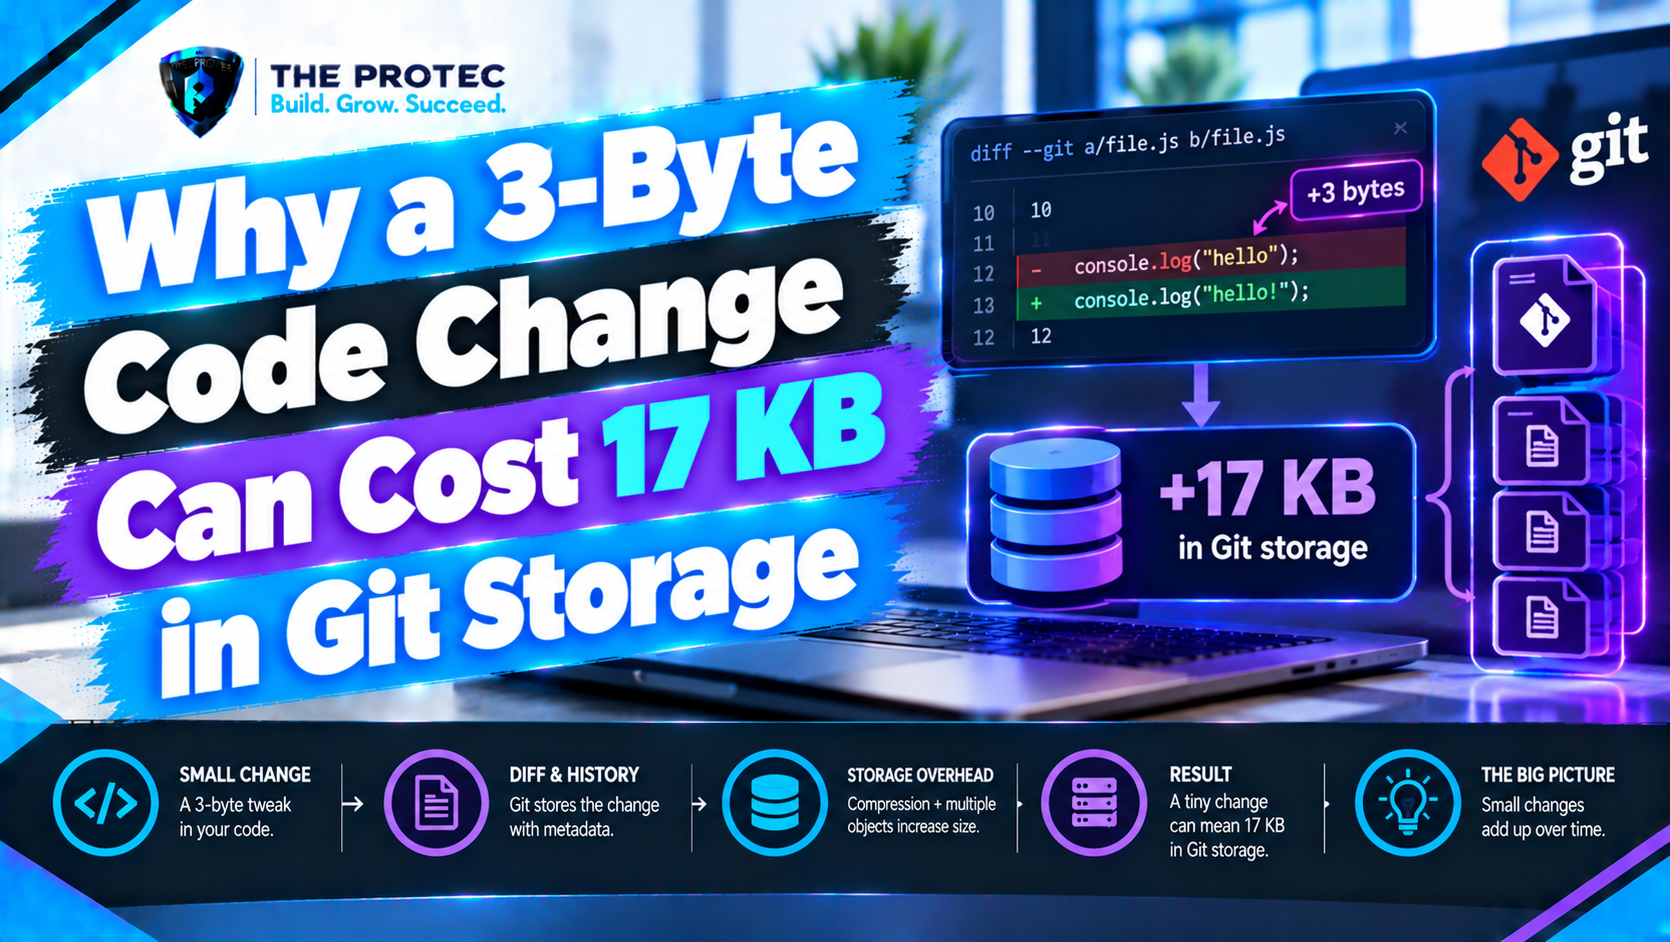
Change three bytes in a source file, commit the edit, and watch the repository grow by 17 KB. That sounds like Git is wasting thousands of bytes for every byte you write. It is also an excellent example of how a technically accurate measurement can become misleading when separated from Git’s storage model.
The reported experiment behind this claim found that a three-byte change added approximately 17 KB to a repository containing 50 files in one directory. Repeating the small edit in a single-file repository reportedly added about 8.7 KB. Those are useful observations from that specific test, not universal estimates of Git commit size.
The original report provided a before-and-after benchmark rather than a complete reproducible repository, raw object inventory, Git version, filesystem configuration, and allocation data. Its methodology is directionally credible: initialize content, record a baseline, change three bytes, commit, and measure the increase. However, the published information is insufficient to independently establish that every measured byte came from Git objects rather than reflogs, the index, references, filesystem block allocation, or rounding. The 17 KB and 8.7 KB values should therefore be attributed to that reported experiment—not treated as constants defined by Git.
To understand how both results are possible, we need to look inside the Git object database.
How big is a Git commit, really?
A logical commit does not have one all-inclusive size. Git does not create a ZIP archive containing every file whenever you commit. Instead, a commit points to a graph of reusable objects. Some objects already exist, while changed content and directory snapshots require new ones.
Consequently, “How big is a Git commit?” can mean at least three different things:
- The uncompressed size of the commit object containing author, timestamp, message, parent, and tree information.
- The sum of newly created Git objects associated with the snapshot.
- The incremental Git repository disk usage, including compressed objects, refs, reflogs, indexes, and filesystem overhead.
These measurements can produce very different answers. A commit object itself is often only a few hundred bytes. The new blob it references could represent a multi-megabyte file. On disk, that blob might occupy only a few kilobytes if it compresses well—or nearly its full size if it is an already-compressed binary.
Git objects explained: blobs, trees, and commits
The foundation of how Git stores commits is its content-addressed object database. Git normally hashes an object’s type, length, and content to produce its identifier. Most existing repositories use SHA-1 object IDs, while Git’s ongoing SHA-256 transition provides a stronger hash format for repositories configured to use it. The storage principles are otherwise similar.
Blob objects store file content
A blob stores the contents of a file, but not its filename. Change three bytes and the content hash changes, so Git creates a new blob. When that blob is initially stored as a loose object, Git compresses the complete new file content with zlib. It does not immediately store only the three changed bytes.
This point explains much of the surprise. If the edited source file is 30 KB, Git may write a compressed representation of the entire 30 KB blob. The resulting loose object might be 7 KB, 15 KB, or more depending on the text. The Git blob size is therefore based on the file’s complete content, not the size of the edit.
Tree objects describe directories
A tree records directory entries: names, modes, object IDs, and whether each entry refers to a blob or another tree. Changing one file changes its blob ID, which means the containing tree must also receive a new ID.
In the 50-file test, the new root tree had to describe all 50 entries even though only one blob reference changed. A single-file repository needed a much smaller tree. This difference offers a plausible partial explanation for why the reported increase was approximately 17 KB in one repository and 8.7 KB in the other.
Nested paths can create additional trees. Editing src/services/payments/handler.js may require new tree objects for payments, services, src, and the repository root because each parent must point to the changed child tree.
Commit objects connect snapshots to history
A commit object references the root tree and usually one or more parent commits. It also contains author and committer identities, timestamps, and the commit message. A normal commit object is small, but it is another new object with compression and storage overhead.
This Git blob, tree, and commit object model means a three-byte edit commonly creates at least three objects: one blob, one tree, and one commit. More trees appear when the edited file is deeper in the directory hierarchy.
Why loose objects can make a tiny edit look expensive
Fresh objects are commonly written under .git/objects as loose objects. Each object receives its own file, compressed using zlib. The object file includes a compressed header identifying the object type and uncompressed length, followed by its data.
Compression helps, but loose objects cannot delta against earlier versions. If two 100 KB source files differ by three bytes, each loose blob is independently compressed. Repetitive source code may compress dramatically, whereas encrypted files, JPEG images, ZIP archives, and many compiled assets may barely compress at all.
Filesystem allocation also matters. A 250-byte loose object can consume a 4 KB block. Three small object files may therefore account for roughly 12 KB of allocated space even though their apparent byte sizes total less than 1 KB. Directory metadata, extended attributes, copy-on-write behavior, and disk block size can alter the result further.
If the benchmark measured the whole .git directory, it may also have captured updates outside the object database. Committing advances a branch reference and appends reflog records. Staging can rewrite the index. A coarse command such as du -sh may round values enough to exaggerate a small difference. These effects are real disk usage, but they are not the size of the commit object.
Git packfiles explained: where delta compression changes the result
Loose objects are convenient for fast writes, not optimal long-term storage. During automatic maintenance or git gc, Git combines objects into packfiles. Packfiles remove much of the per-file filesystem overhead and can represent similar objects using Git delta compression.
Instead of storing two complete versions of a large source file, a pack may store one as a base and the other as instructions describing differences. A three-byte edit can then require a very small delta, although object headers, indexes, checksums, and alignment still add overhead. Git chooses delta relationships heuristically; a version is not guaranteed to delta directly against its immediate predecessor.
This is why Git loose objects vs packfiles is central to the experiment. The same logical commit may initially add 17 KB of allocated disk space but contribute far less after packing. Conversely, a binary file with no useful similarity may remain large in a pack.
Modern large-repository optimization also uses features such as multi-pack indexes, cruft packs, partial clones, and background maintenance. These improve scale and object management, but they do not change the core fact that content, repository shape, and maintenance state determine physical storage.
How to measure Git repository disk usage correctly
Start with Git’s own object statistics:
git count-objects -vH
The output separates loose object count and size from pack count, pack size, garbage, and prune-packable objects. Run it before the edit, after committing, and after garbage collection. It is more informative than a single directory total, although it does not account for every byte in refs, reflogs, hooks, or the index.
Inspect the uncompressed size of individual objects with:
git cat-file -s HEAD
git cat-file -s HEAD^{tree}
git cat-file -s HEAD:path/to/file
The first command reports the commit object’s payload size, the second reports the root tree size, and the third reports the current blob size. Use git ls-tree -r HEAD to discover object IDs and file paths.
For total disk allocation, compare:
du -sk .git
On systems supporting GNU options, contrast allocated and apparent size:
du -s -B1 .git
du -s -B1 --apparent-size .git
Then pack reachable objects and measure again:
git gc
A rigorous Git storage benchmark should record the Git version, operating system, filesystem, allocation unit, exact file contents, commit message, hash format, measurement command, and whether maintenance ran. It should also distinguish object database growth from total .git growth. The official Git Internals documentation provides additional detail on object construction.
Why Git repositories grow unexpectedly
Ordinary source history is usually not the main problem. Text compresses well, and similar revisions often delta efficiently. Repository growth accelerates when teams commit generated bundles, dependency directories, database dumps, archives, videos, design exports, or frequently changing binaries.
Deleting a large tracked file in a later commit does not remove its earlier blob. The history must still reproduce the old snapshot, so clones continue to receive that content unless partial-clone filters or history rewriting intervene. Build systems and AI-assisted development can amplify this issue by producing more generated code, model artifacts, caches, and machine-created assets that should not enter normal Git history.
How to reduce Git repository size safely
- Ignore generated output. Add build directories, caches, logs, coverage reports, and downloaded dependencies to
.gitignorebefore they are committed. - Keep large binaries elsewhere. Use artifact repositories, release storage, or Git LFS for assets that need versioned pointers without living as normal Git blobs.
- Run appropriate maintenance. Git usually performs automatic housekeeping, but
git gccan consolidate loose objects after object-heavy operations. Do not run aggressive garbage collection routinely without measuring the cost and benefit. - Find the real offenders. Inspect pack statistics and large historical blobs rather than assuming commit count is the problem.
- Use partial clone and sparse checkout when suitable. These features can reduce local transfer and working-copy costs for very large repositories, even though they do not erase server-side history.
- Rewrite history only with a plan. Tools such as git-filter-repo can remove large historical objects, but rewritten commit IDs disrupt open branches, forks, tags, and existing clones. Coordinate the migration and expire old server references when the savings justify that disruption.
FAQ: Git commit size and storage
Does every Git commit consume 17 KB?
No. The 17 KB figure belongs to one reported 50-file experiment measured under a particular, incompletely documented environment. Another test in the same report produced about 8.7 KB. A real commit may add hundreds of bytes, several kilobytes, or gigabytes depending on changed content, trees, compression, filesystem allocation, and packing state.
Does Git save an entire file after every edit?
Logically, each changed file produces a new full-content blob. As a loose object, that blob is independently zlib-compressed. After packing, Git may store it as a delta against a similar object, making the physical representation much smaller.
Why can a large source file use surprisingly little space?
Source code often contains repeated identifiers, whitespace, syntax, and structural patterns that compress effectively. Closely related versions are also strong candidates for delta compression. File size alone therefore does not predict packed Git storage.
Does git gc delete commit history?
Normal git gc packs reachable objects and cleans unreachable data according to expiration policies. It does not delete reachable commits. Objects retained by branches, tags, reflogs, or other references remain available.
What is the best definition of Git commit size?
There is no single best definition. For investigations, report the commit object size, newly created object payloads, loose-object disk allocation, and post-pack incremental size separately. That makes the result reproducible and prevents filesystem overhead from being mistaken for history content.
The key lesson
The remarkable part of the three-byte experiment is not that Git imposes a fixed 17 KB tax. It is that storage has layers. A tiny edit can create a full new blob, replacement trees, a commit object, reflog entries, and several separately allocated files. Later, packfiles and delta compression can transform that footprint again.
When evaluating Git repository size, ask what was measured, when it was measured, and whether the objects were loose or packed. Once those questions are answered, the apparently absurd result becomes a practical Git internals tutorial—and a reminder that logical change size and physical storage cost are not the same thing.