A call such as malloc(100) looks almost trivial, but understanding how malloc works reveals a sophisticated subsystem between your program and the operating system. The allocator must find suitably aligned space, record its ownership, reuse freed blocks, limit fragmentation, handle concurrent threads, and sometimes obtain more pages from the kernel. Most calls do not enter the kernel at all. That hidden machinery can materially affect a C program’s speed, memory footprint, reliability, and security.
The precise implementation varies by C library and allocator, but the common path is straightforward: round the requested size to an appropriate internal size, search reusable memory, split a larger block if necessary, and ask the operating system for more memory only when existing supplies cannot satisfy the request.
Following a simple C malloc function call
Consider a small allocation:
#include <stdio.h>
#include <stdlib.h>

int main(void) {
    int *values = malloc(100 * sizeof *values);
    if (values == NULL) {
        perror("malloc");
        return EXIT_FAILURE;
    }

    values[0] = 42;
    free(values);
    return EXIT_SUCCESS;
}
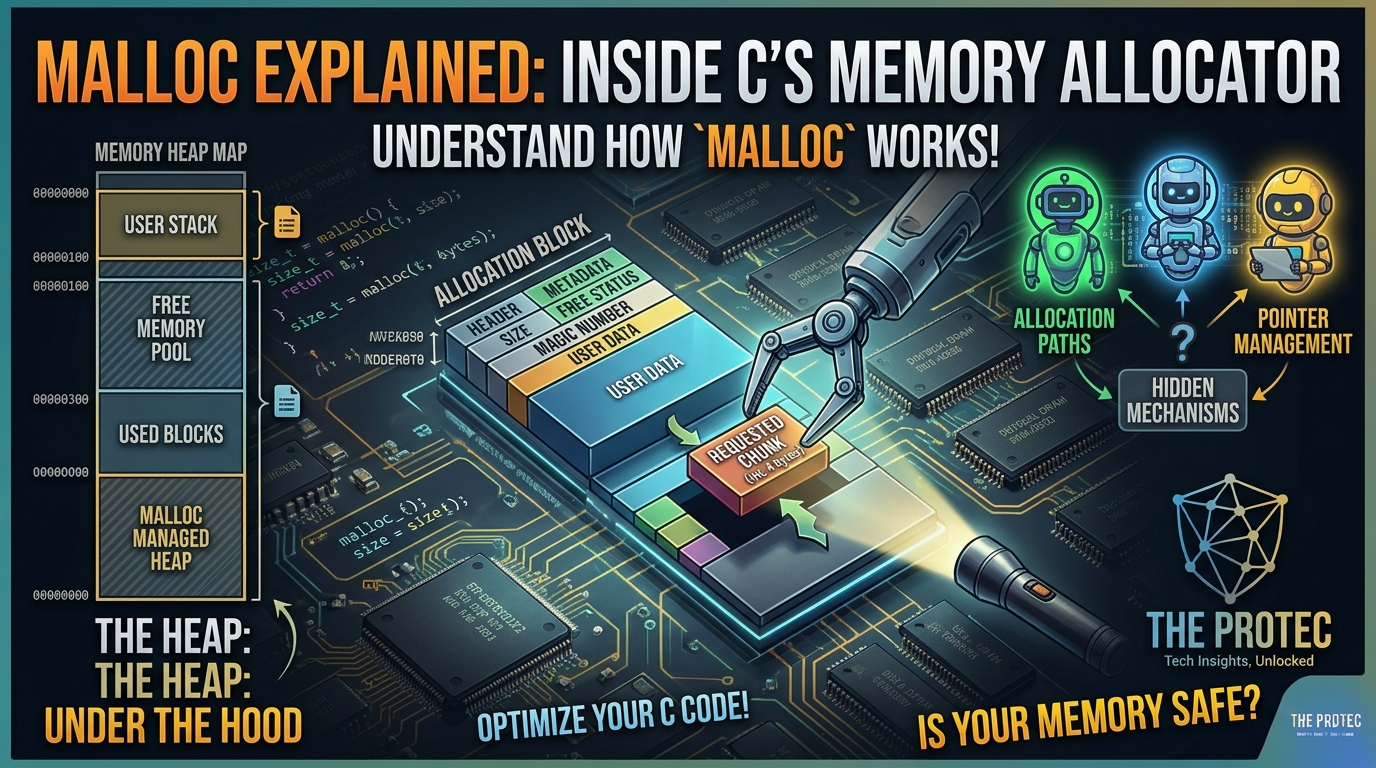
The program requests enough space for 100 integers. The allocator does not necessarily reserve exactly that many bytes. It may round the request upward for alignment, map it to a size class, and account for metadata. A conceptual block might look like this:
+----------------------+-----------------------------+
| size/status metadata | bytes returned to caller    |
+----------------------+-----------------------------+
                       ^
pointer returned by malloc()Metadata can record the block’s size, whether neighboring blocks are free, or links used while the block is on a free list. This diagram is illustrative: some allocators store metadata beside allocations, while others keep some or all of it separately.
If a suitable free block exists, the allocator removes it from a list or bin. If that block is significantly larger than requested, it may split it:
Before: [------------- available block -------------]
After:  [ allocated block ][ remaining free block   ]
The returned pointer is aligned suitably for objects with fundamental alignment requirements. The bytes are uninitialized, so reading them before writing a value is an error. calloc(), by contrast, requests an array and initializes its bytes to zero while also checking the element-count multiplication for overflow.
Heap memory explained: heap versus stack
The stack normally stores automatic variables, saved registers, and function-call state. Allocation and release are tied to control flow: returning from a function effectively discards its stack frame. Stack operations are therefore extremely cheap, but stack space is limited and an object’s lifetime cannot naturally extend beyond its scope.
Dynamic memory allocation in C serves a different need. Heap objects remain allocated until they are passed to free(), allowing their lifetime and size to be determined at runtime. “Heap” in this context means memory managed by the allocator; it should not be confused with the heap tree data structure. Modern allocators may manage several arenas and many separate virtual-memory mappings rather than one tidy, contiguous heap.
Why malloc is not a system call
malloc() is a C library function and allocator interface, not a direct kernel service. A kernel can provide pages and virtual address mappings, but it does not usually manage every 24-byte or 200-byte object in a process. Crossing into the kernel for every allocation would be expensive and would provide none of the fine-grained reuse that applications need.
Instead, the allocator acquires memory in larger units and subdivides it in user space. On Unix-like systems, two historically important mechanisms are brk() and mmap(). Other operating systems expose different virtual-memory APIs.
brk vs mmap
brk(): Changes the end of the process’s traditional data segment. This can extend a contiguous heap region, from which the allocator creates smaller blocks.mmap(): Creates an independent virtual-memory mapping. Allocators commonly use anonymous mappings for large allocations, arenas, or extents.
A typical allocator can use both. Small allocations may come from an arena backed by previously acquired pages, while a sufficiently large request may receive a dedicated mapping. The cutoff is implementation-dependent and may be adjusted dynamically, so applications should not rely on one fixed threshold.
Virtual address space also differs from physical memory. Reserving or mapping an address range does not necessarily mean that every page immediately occupies RAM. The operating system commonly supplies physical pages on first access through page faults. For the standard interface and edge-case requirements, see the Linux malloc(3) documentation.
Free lists, bins, size classes, and arenas
Scanning every free block would make allocation progressively slower. Allocators therefore organize reusable blocks. Simple designs use linked free lists; production allocators generally add bins, trees, bitmaps, or size classes.
A size-class design groups similar requests:
Class 16:  [free] -> [free]
Class 32:  [free] -> [free] -> [free]
Class 64:  [free]
Large:     indexed by exact or approximate size
A 27-byte request might be served from a 32-byte class. This wastes a few bytes but makes lookup fast and predictable. Thread-local caches can make common allocations even faster because a thread can often obtain a block without taking a global lock.
An arena is a separately managed allocation region. Multiple arenas reduce lock contention when many threads allocate simultaneously. The trade-off is that memory available in one arena may not satisfy demand in another, increasing the process’s retained memory and potential fragmentation.
Why free does not always return memory to the OS
free(pointer) tells the allocator that the block may be reused. It does not promise an immediate system call or an instant reduction in the process’s resident memory.
The allocator may place the block in a thread cache or free list. It may coalesce adjacent free blocks into a larger region:
[ free A ][ free B ] -> [ larger free region ]Keeping memory is often beneficial because a later malloc() can reuse it without kernel involvement. Returning memory can also be impossible when a free block is surrounded by live allocations. For suitable page-aligned regions, an allocator may unmap memory or advise the kernel that pages can be reclaimed while retaining the virtual address range. Large dedicated mappings are generally easier to release than scattered small blocks.
This distinction explains why a program’s operating-system memory metrics may remain high after it frees many objects. The memory can be free from the allocator’s perspective while still belonging to the process.
Internal and external memory fragmentation
Internal fragmentation is unused space inside an allocated block. If a 33-byte request is rounded to a 48-byte class, the extra bytes are unavailable to other allocations. Alignment and metadata can add more overhead.
External fragmentation occurs when total free memory is sufficient but divided into pieces that cannot satisfy a large contiguous request. For example, three separated 1 KiB holes cannot necessarily serve one 3 KiB allocation.
Allocation patterns matter. Long-lived objects interspersed with short-lived objects can prevent coalescing or page release. Size classes, extent management, decay policies, and compaction-like techniques for allocator metadata can reduce waste, but C allocators generally cannot move live objects because programs hold raw pointers to them.
The allocator manages storage; it does not automatically enforce object ownership or array bounds. Common failures include:
- Memory leak: The program loses every pointer to a live allocation without freeing it.
- Double free: The same allocation is freed twice, potentially corrupting allocator metadata.
- Use after free: Code accesses a block after ownership has ended. The block may already contain another object.
- Heap buffer overflow: A write passes the allocation boundary and may damage neighboring data or metadata.
- Invalid free: Code passes an interior, stack, static, or otherwise invalid pointer to
free().
These are correctness and security vulnerabilities, not merely cleanup issues. Modern allocator hardening can detect some corrupted states or protect free-list links, but it cannot make unsafe accesses valid. Programs still need clear ownership rules, bounds checks, overflow-safe size calculations, and disciplined cleanup paths.
How glibc malloc, jemalloc, and tcmalloc differ
No single strategy wins for every workload. Modern memory allocator internals are shaped by allocation sizes, thread counts, latency requirements, and acceptable memory overhead.
- glibc malloc: Derived from the ptmalloc family, it uses arenas, multiple categories of bins, per-thread caches, and both heap growth and mappings. It aims to serve general Linux workloads while preserving the standard C interface.
- jemalloc: Emphasizes size classes, arenas, extent management, profiling, and fragmentation control. It is widely used where predictable multithreaded behavior and detailed allocator statistics are valuable.
- tcmalloc: Uses front-end caches for fast common allocations, central coordination, and page-oriented back ends. Its design focuses heavily on scalable allocation in multithreaded applications.
The details evolve, but the broad trend is clear: hot allocation paths increasingly rely on thread- or CPU-local caching, while background or less frequent paths handle page acquisition, purging, statistics, and reclamation. Local caches reduce contention but can retain more memory. Aggressive purging lowers footprint but may increase page faults and latency later.
Changing allocators can improve malloc performance, but benchmarks must reproduce the application’s real object sizes, lifetimes, thread behavior, and steady-state load. A synthetic loop that repeatedly allocates and frees one size rarely captures production fragmentation or contention.
Practical C programming debugging tools
Valgrind Memcheck
On supported platforms, Memcheck can report leaks, invalid reads and writes, use of uninitialized values, and incorrect frees. A typical command is valgrind --leak-check=full ./app. It is thorough but substantially slows execution, making focused test cases preferable.
AddressSanitizer
Compile with options such as -fsanitize=address -g -fno-omit-frame-pointer, then run the instrumented program. AddressSanitizer uses compiler instrumentation and protected shadow memory to catch heap overflows, use-after-free errors, and related defects. The LLVM AddressSanitizer documentation describes supported checks and limitations.
Heap profiling
Heap profilers answer a different question: which call paths allocate or retain the most memory? Allocator-native profiling, sampling profilers, and application metrics can expose growth that is technically reachable but operationally wasteful. Capture profiles after warm-up and over representative workloads; startup allocations alone can be misleading.
For difficult corruption bugs, combine sanitizers with assertions, deterministic tests, and allocator diagnostics. Reproduce the earliest invalid access rather than investigating only the later crash inside malloc() or free(), where damaged metadata is finally noticed.
What programmers should remember
A small allocation usually comes from memory the allocator already controls. The fast path may be little more than a size-class lookup and pointer update, while the slow path may split blocks, consolidate free space, extend an arena, create a mapping, or reclaim pages. Minimize needless allocation in hot loops, check failures, pair ownership with cleanup, and measure before replacing an allocator.
Frequently asked questions
Does every malloc call request memory from the kernel?
No. Most requests are served from existing arenas, free lists, or thread caches. Kernel interaction is generally reserved for replenishing the allocator’s larger memory pools or handling requests that merit separate mappings.
Does free immediately reduce a process’s RAM usage?
Not necessarily. The allocator may retain the block for reuse, and fragmented pages may still contain live objects. Suitable large or page-aligned regions can sometimes be unmapped or made reclaimable.
Is malloc memory always located in one heap segment?
No. A process can have a traditional data-segment heap, multiple allocator arenas, and separate anonymous mappings. “Heap memory” is a useful programming abstraction, not a guarantee of one contiguous region.
Which allocator is fastest?
There is no universal winner. Results depend on allocation sizes, object lifetimes, thread contention, fragmentation, cache behavior, and memory limits. Benchmark glibc malloc, jemalloc, tcmalloc, or another candidate under a realistic application workload.